Learning Interaction between Image and Layout Priors for Joint Image-Layout Generation in Design Templates
IEEE Transactions on Visualization and Computer Graphics · 2026
A joint diffusion framework that learns how pretrained image and layout models communicate instead of asking one modality to follow the other.
01 / Research problem
Sequential generation hides the dependency.
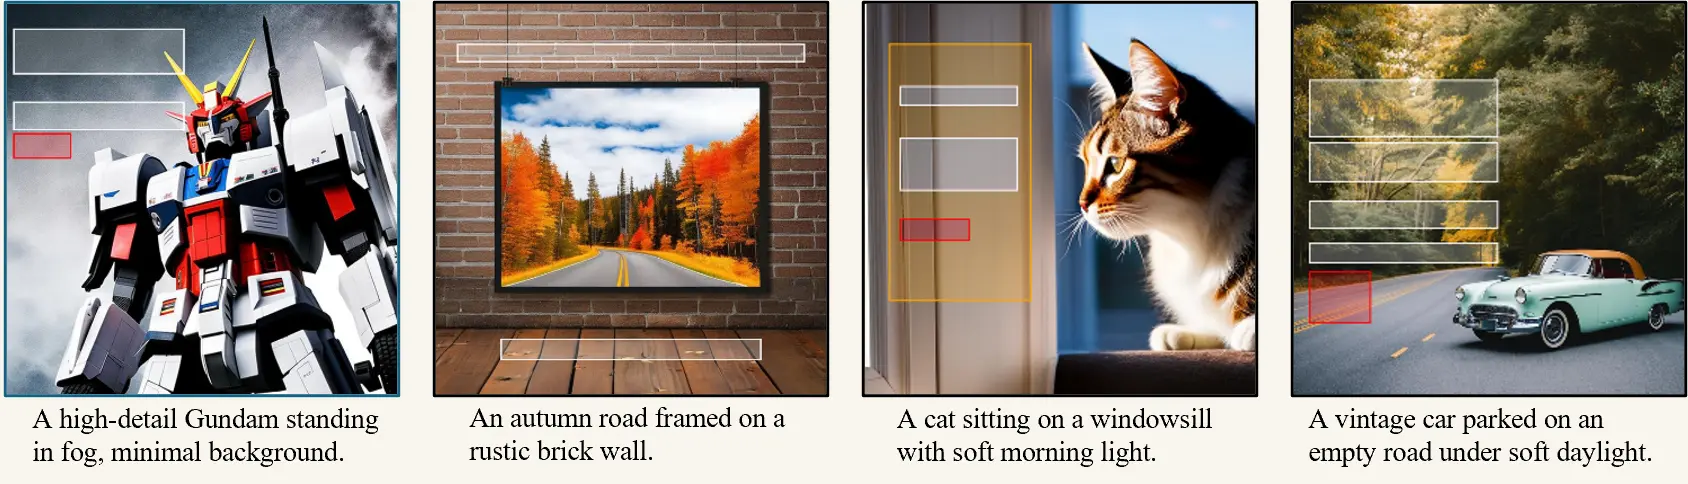
A background image and its foreground layout are not independent outputs: composition, empty space, visual saliency, and semantic intent constrain both. Sequential pipelines generate one modality first and force the second to adapt to a decision that can no longer change.
InterIL models the two modalities in a single generative process. The aim is not to replace strong pretrained priors, but to teach them when and what to exchange while their predictions are still evolving.
02 / Approach
Freeze the priors; learn the interaction.
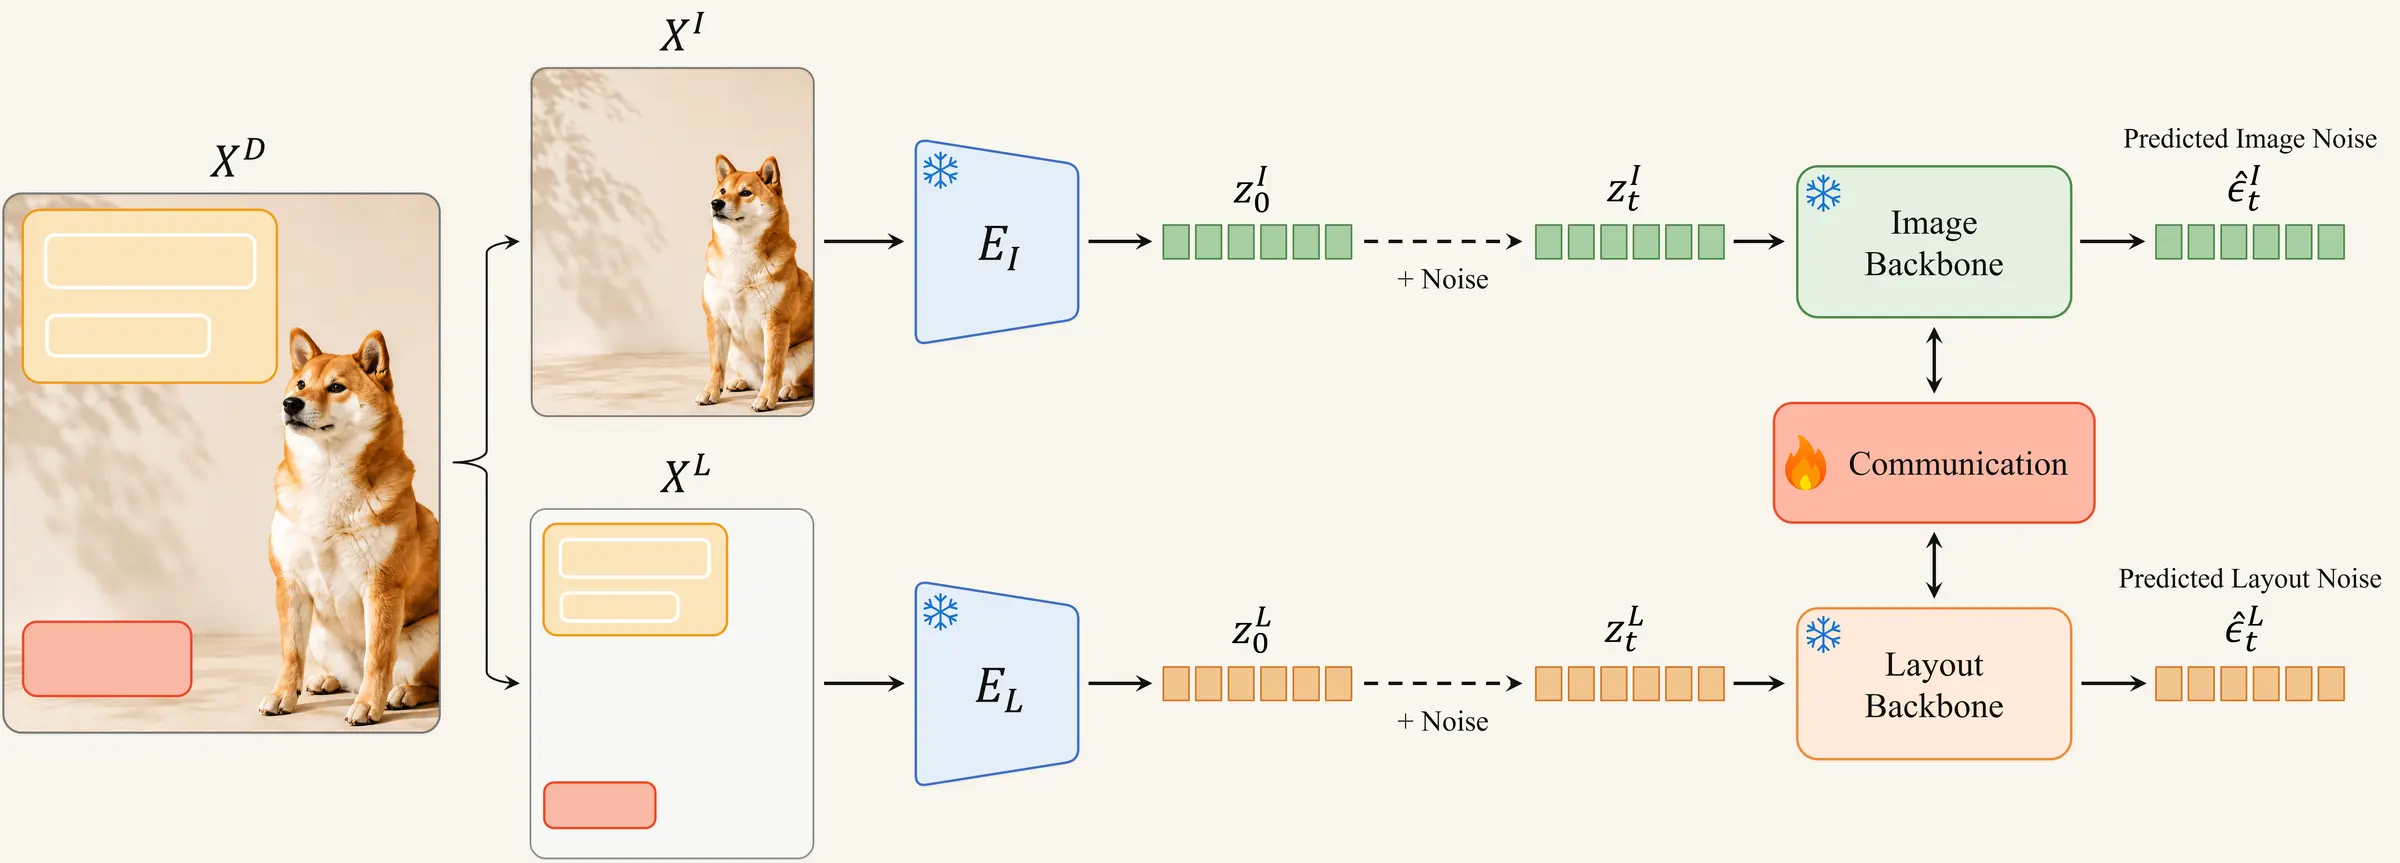
InterIL connects frozen image and layout diffusion backbones with a lightweight bidirectional communication module. The module is trained to move useful signals across the two denoising trajectories while retaining the knowledge already encoded by each backbone.
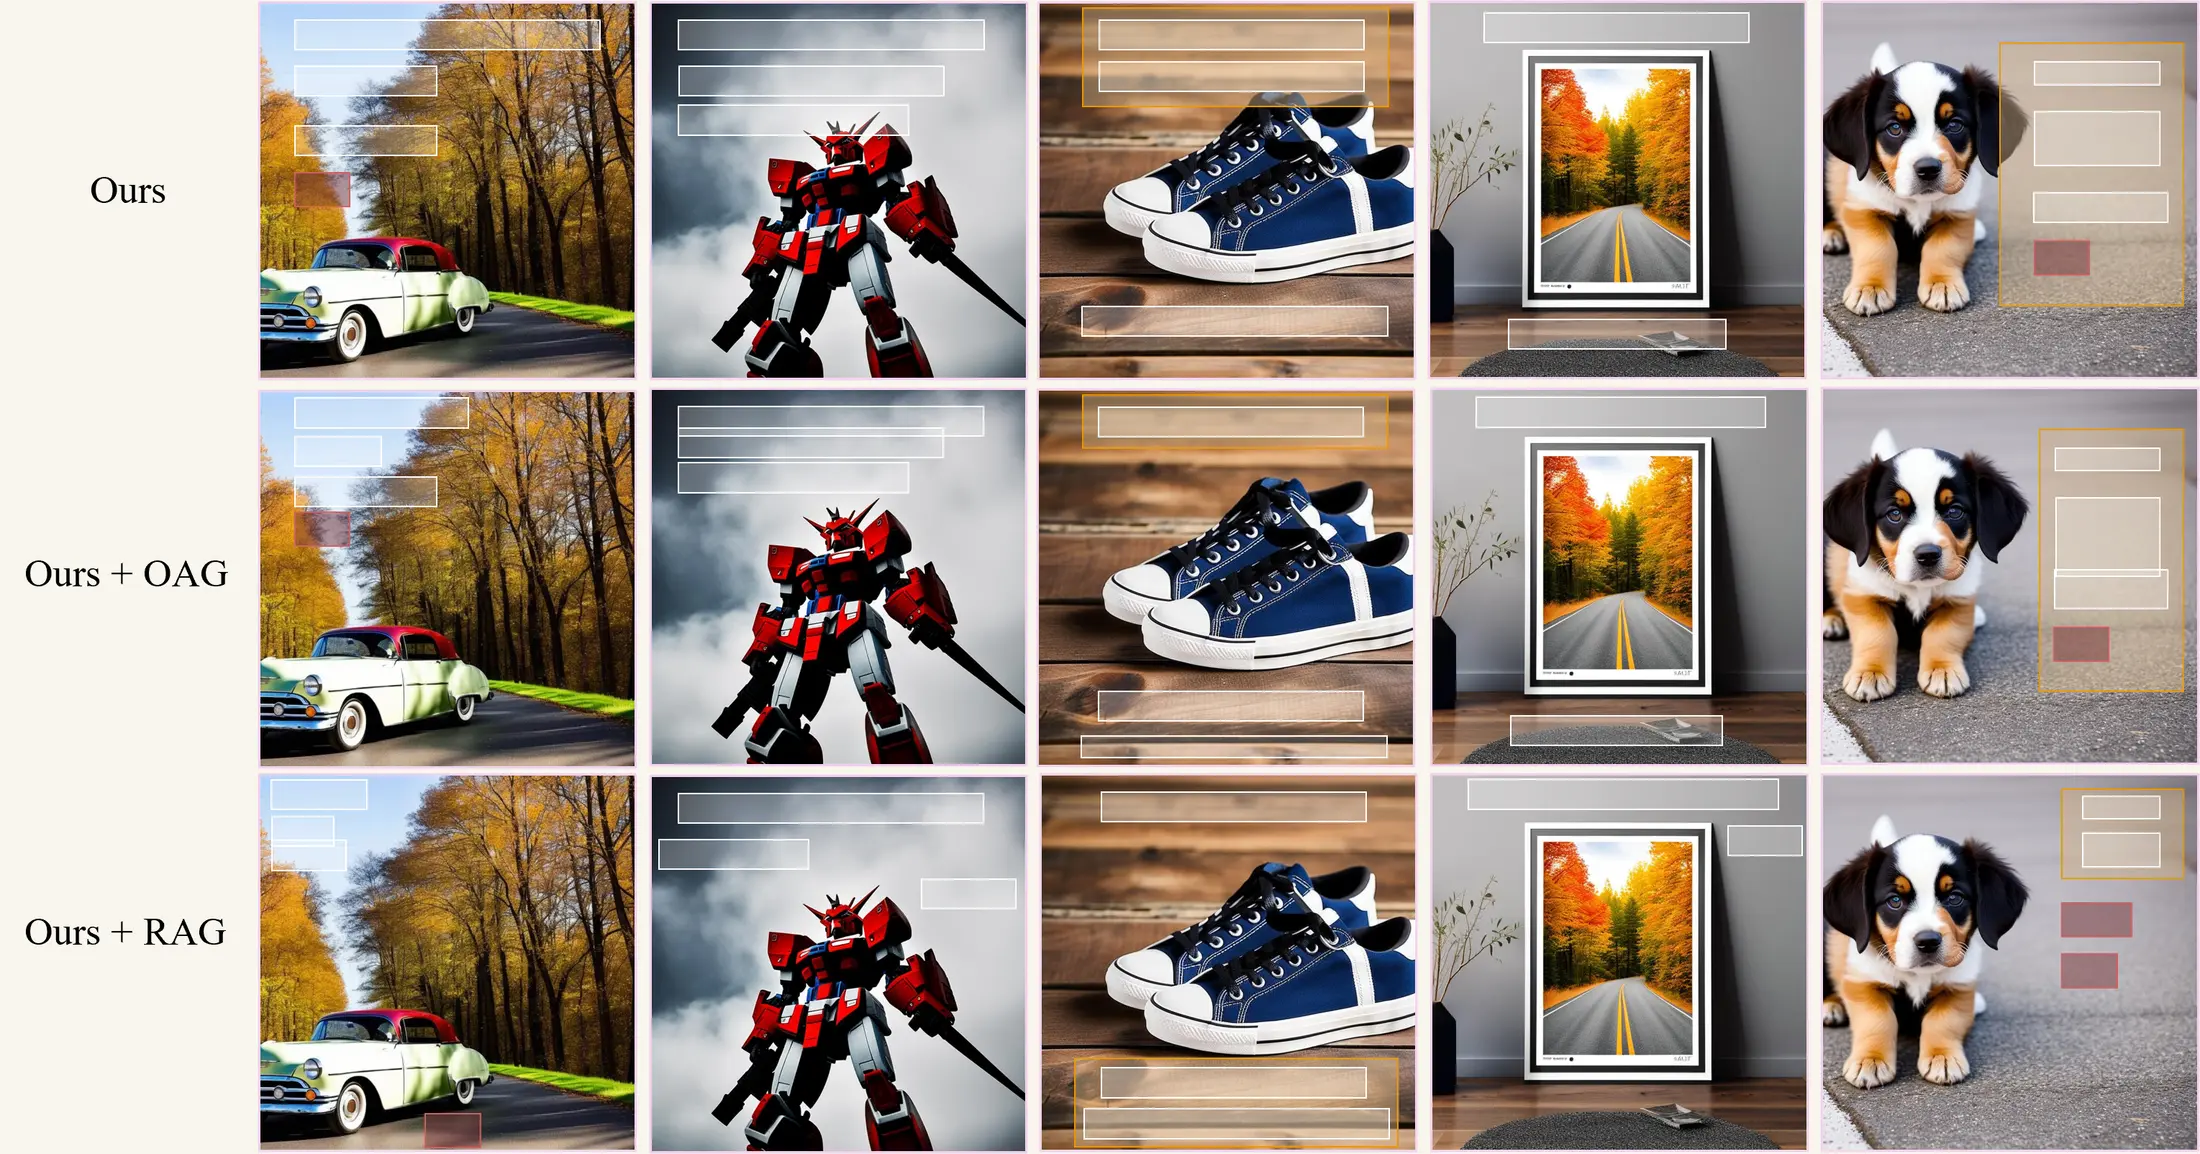
At inference time, guidance can adjust the balance between image fidelity and layout preference without retraining the two generators.
03 / At a glance
What this project adds.
- 01
Introduces a joint image-layout generation paradigm for design templates rather than a fixed sequential pipeline.
- 02
Learns explicit bidirectional interaction between frozen pretrained image and layout diffusion priors.
- 03
Supports inference-time guidance for different image-layout preferences without updating the backbones.
04 / Publication status